



It is 2 a.m. The pager goes off. Checkout is down, customers are dropping, and you have five dashboards open across four tools that do not agree. One says the application is fine. Another says latency is climbing. None tells you why.
This is the moment that decides whether you have the right application performance monitoring tool. Modern applications run across containers, cloud services, APIs, and infrastructure spanning on-premises and multiple clouds. A failure in one layer often masquerades as a problem in another.
When choosing an APM tool, evaluate whether it can follow critical transactions end to end, measure real user experience, correlate applications with infrastructure, and identify actionable root causes. Also compare technology and cloud coverage, automatic discovery, scalability, integrations, deployment flexibility, operational effort, reporting, and the total cost of monitoring the environment at full scale.
What is an APM Tool and What Does It Do?
Definition and Core Purpose
An application performance monitoring tool measures how well your applications run and helps you find and fix problems that hurt performance or availability. Its purpose is simple to state and hard to deliver: tell you what is slow, why, and where to fix it, before the business is affected.
How Do APM Tools Work?
APM platforms collect telemetry from inside and around your applications: instrumenting code to capture transactions, often watching the infrastructure underneath, and observing real users. That data is correlated and baselined so deviations stand out, turning raw signals into clear answers.
Key Metrics Collected by APM Platforms
Most platforms track a consistent set of signals that describe application health:
- Response time: how long a request takes to complete, measured end to end and per tier.
- Throughput: the volume of requests or transactions handled over a period.
- Error rates: the share of requests that fail, time out, or return faults.
- User transactions: the real journeys, such as login or checkout, that map to business outcomes.
Together, these show not just that something changed, but whether it matters.
Why Businesses Need Application Performance Monitoring Tools
Detecting Performance Bottlenecks Faster
When a transaction slows, the cause could sit in code, a database query, a third-party API, or the infrastructure underneath. The right application performance monitoring tool narrows that search from hours to minutes, which means lower mean time to resolution. Digital experience monitoring enables businesses to enhance application performance, and proactively address issues, ultimately driving improved customer satisfaction and business outcomes.
Improving User Experience Across Applications
Users do not care about server CPU or cloud infrastructure performance. They care whether the page loads and the transaction completes. Application monitoring tools that measure the user’s experience catch slow pages and regional issues that backend metrics miss. APM features such as session replay also allow businesses to gain valuable insights into customer behavior.
Reducing Downtime and Service Disruptions
Downtime is expensive, and partial degradation can be worse because it is harder to spot. Intelligent baselines flag abnormal behavior early, so teams act before a slowdown becomes an outage. Even a slight delay in page load time translates into lost revenue, poor customer satisfaction and negative brand impact. For example:
- As explained in a blog by GigaSpaces, a one second increase in page load time for Amazon translates into a 1% drop in sales (about $1.6 billion in sales annually).
- Google found that a delay of 0.5 seconds in search page load time dropped traffic by 20%.
Supporting Hybrid and Cloud-Native Applications
Workloads can span physical servers, virtual machines, containers, private cloud, and public cloud at once. Effective transaction tracing follows a transaction wherever it runs, without losing the thread.
How to Choose an APM Tool
Start with the applications and business transactions that matter most, then map the technologies and environments the tool must cover. Shortlist platforms that provide full-stack visibility, usable root-cause analysis, user-experience monitoring, automation, and integrations. Validate each option with representative workloads, confirm deployment effort and data retention, and compare total cost at expected scale.
APM Tool Evaluation Checklist
- Full-stack visibility from users and transactions to applications and infrastructure
- Coverage for required on-premises, cloud, hybrid, container, and Kubernetes environments
- Automatic application and service discovery
- Dynamic dependency mapping
- Accurate, explainable root-cause analysis
- Real-user and synthetic monitoring
- Integrations with ITSM, alerting, collaboration, and development tools
- Scalable collection, analytics, retention, and administration
- Automated baselines, anomaly detection, alert correlation, and remediation options
- Operational and executive reporting
- Flexible SaaS and on-premises deployment
Key Features to Look for When Choosing an APM Tool
Real-Time Transaction Monitoring
See transactions as they happen, not in a report the next morning. Real-time monitoring surfaces slow or failing transactions while you can still act on them.
Distributed Tracing for Microservices
In a microservices architecture, one request can touch dozens of services. Distributed tracing follows it across every hop, showing where time is spent and where it breaks. OpenTelemetry has emerged as the open standard for instrumentation and trace-context propagation, which matters to teams avoiding vendor lock-in.
AI-Powered Root Cause Analysis
Dashboards show symptoms. Root cause analysis explains them. AI and machine learning learn normal behavior, detect anomalies automatically, and correlate related events so the real cause is not buried under downstream alerts.
Infrastructure and Application Correlation
An application slowdown is often an infrastructure problem in disguise. Correlating application metrics with the servers, clouds, databases, storage, and network beneath them separates a guess from an answer.
Digital Experience Monitoring
Digital experience monitoring combines real user monitoring, which captures actual sessions, with synthetic monitoring, which runs scripted tests around the clock. Together they tell you how the application feels to real users in every location.
What to Consider Before Choosing an APM Tool
Monitoring Multi-Cloud Environments
Each cloud has its own native tools, metrics, and blind spots. Stitching them into one coherent view is hard, and the gaps between them are exactly where problems hide. Learn more about the requirements for effective cloud monitoring, see: White Paper | Top 10 Requirements for Performance Monitoring of Cloud Applications and Infrastructures.
Handling Dynamic Microservices Architectures
Containers and services scale up, move, and disappear within minutes. Monitoring has to keep pace and map dependencies that change constantly. APM monitoring tools must auto-deploy and auto-discover alongside the technologies they monitor.
Identifying Root Causes Across Dependencies
Modern applications depend on long chains of services and infrastructure. When one link degrades, symptoms appear everywhere, and isolating the true cause is the central difficulty of APM.
Alert Fatigue and Noise Reduction
When every tool alerts independently, a single incident generates hundreds of notifications (an alert storm), and the one that matters gets lost. Reducing noise through correlation and intelligent baselining is now a core requirement.
Limitations of Distributed Tracing
While distributed tracing is a powerful technique for monitoring and analyzing the performance of distributed systems, there are some limitations to what it can do. Here are some scenarios where distributed tracing may not be enough:
- Not all tracing tools provide automatic instrumentation: Distributed tracing is intended to save teams time and effort; however, some tools require developers to manually instrument or adjust their code to configure distributed tracing requests. This can be time-consuming and can result in code errors.
- Tracing is not enough on its own: Distributed tracing provides visibility into the performance of individual components of a distributed system, but it may not provide enough context to understand the system. For example, distributed tracing may not capture the impact of network latency or infrastructure bottlenecks that affect the system’s performance.
- Limited to backend coverage: Many tools do not take an end-to-end approach to distributed tracing and only generate a trace ID for a request when it reaches the first back-end service, losing information pertaining to the user session on the frontend.
APM Tool Pricing and Total Cost of Ownership
The licensing models of APM tools varies wildly and costs can be prohibitive at scale. Pricing models based on a per transaction basis or resource configurations (e.g. size of server) can prove particularly challenging for many organizations to deploy at the scales they need for effective full-coverage visibility of all their apps. Many APM products require additional modules to provide functionality such as infrastructure or database monitoring which can also inflate costs.
APM Tool Implementation Best Practices
Define Critical Business TransactionsMonitor End-User Experience
Instrument the experience, not just the backend. Combine real user and synthetic monitoring so you know how the application performs for actual users and can catch issues before they report them.
Integrate Infrastructure and Application Monitoring
Do not monitor applications and infrastructure in separate tools. When the two are correlated in one place, you can trace a slow transaction straight down to the resource causing it.
Use Automation for Faster Remediation
Automation closes the gap between detection and resolution. Automated diagnosis and remediation at the infrastructure and server level can resolve common issues before someone has to wake up.
How eG Enterprise Supports APM Requirements
End-to-End Application Visibility
eG Enterprise gives IT teams a single, unified view spanning the application and the infrastructure it runs on. Instead of switching between tools, you see the entire transaction path in one console, which turns a 2 a.m. scramble into a quick, confident fix. Its digital experience monitoring adds real user and synthetic monitoring, Core Web Vitals, and session replay to reconstruct a user’s full journey.
Full Stack Monitoring and Correlation
eG Enterprise monitors 650+ applications and technologies out of the box, from databases, Java, .NET, and PHP to SAP, Oracle, Docker, Kubernetes, and Citrix. It correlates application performance with the underlying physical, virtual, cloud, and hybrid infrastructure, so a slowdown is traced to its real cause rather than its loudest symptom.
AI-Driven Performance Analytics
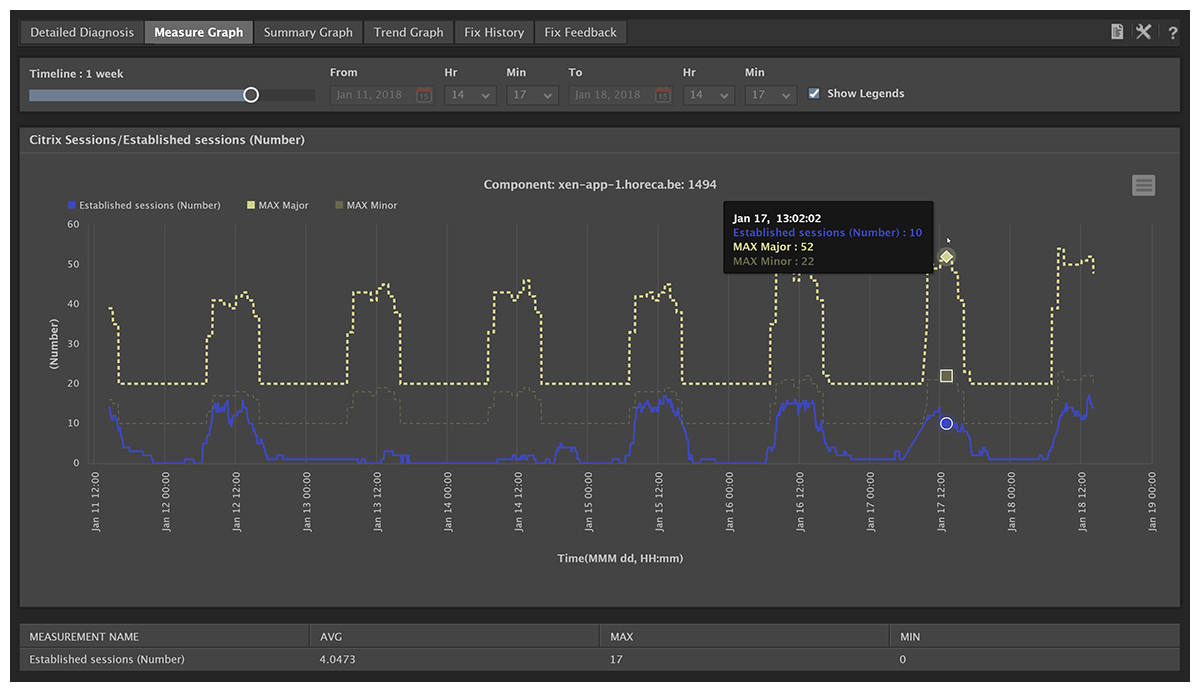
Using AIOps with machine-learning auto-baselining and anomaly detection, eG Enterprise learns what normal looks like for your environment and flags deviations early. Predictive forecasting supports capacity planning, helping you right-size resources before demand outpaces them.
Cross-Tier Dependency Mapping
eG Enterprise traces each transaction through every tier using byte-code instrumentation with a tag-and-follow approach, with no application code changes. eG Enterprise gives a complete visualization of the transaction flow across every tier of the application architecture (web server, application server, database, message queues, and remote calls).
It pinpoints the responsible Java method, SQL query, or external API call and builds the dependency map automatically, keeping that picture accurate as the environment changes.

Application Discovery & Dependency Mapping
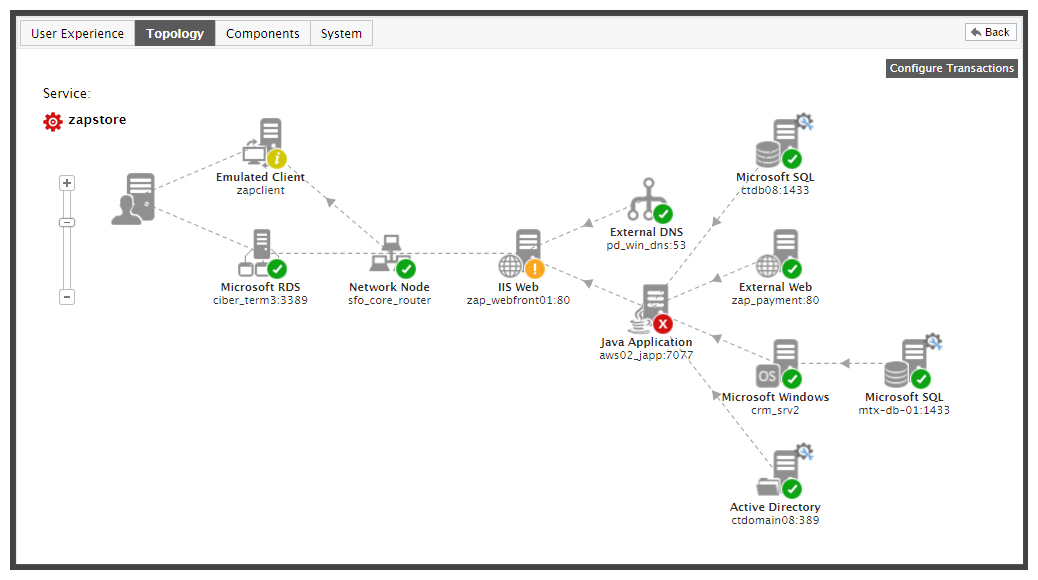
eG Enterprise will automatically discover and visualize application topologies, showing real-time service dependencies across cloud, container, virtual, and on-premises infrastructures. It uses AI-assisted root cause diagnosis technology to accurately pinpoint the reason for application slowness. eG Enterprise will also correlate front-end slowness with API latency, database query times, and container resource exhaustion.
Application Analytics & Reporting
eG Enterprise gives actionable insights through intelligent alerting, anomaly detection, and adaptive baselining powered by self-learning. The built-in analytics dashboards help surface trends, patterns, and emerging risks across the IT landscape. You can use them out-of-the-box and customizable reports for historical analysis, capacity forecasting, cost optimization, right-sizing, auditing, and executive-level visibility. This enables data-driven decisions by IT and business stakeholders.
Learn more about eG Enterprise’s predictive analytics, see: Predictive Analytics Models and Algorithms for IT Systems and Metrics | eG Innovations.
Cost-effective, Flexible APM
eG Enterprise’s unique features include a simple and predictable licensing model based on technologies and applications monitored (not by volume of transactions or resource configuration) and flexible deployment – on-premises or cloud-based.
Quick Snapshot – What to Look in an APM Tool
| Capability | Why It Matters | What to Evaluate |
| Application coverage | Comprehensive application coverage ensures every critical business service is monitored, helping teams avoid blind spots that can hide performance issues, outages, or user-impacting problems. Broad visibility is essential for maintaining service reliability across modern, complex environments. | Supported programming languages, frameworks, packaged applications, databases, cloud services, microservices, and the ease of onboarding new technologies into the monitoring platform. |
| Transaction tracing | Transaction tracing helps pinpoint exactly where latency, bottlenecks, and errors occur, reducing troubleshooting time and enabling faster resolution of application performance issues before they impact users. | End-to-end visibility across application tiers, support for distributed tracing, code instrumentation requirements, trace sampling methods, and visibility into third-party APIs and external service dependencies. |
| User experience | Understanding the actual user experience ensures IT teams measure service quality from the end user’s perspective rather than relying solely on backend infrastructure metrics. | Availability of real user monitoring (RUM), synthetic testing, browser and device visibility, geographic performance insights, session analytics, and user journey tracking capabilities. |
| Root-cause analysis | Effective root-cause analysis accelerates problem resolution by identifying the underlying source of issues rather than simply reporting symptoms across different technology layers. | Cross-tier dependency mapping, automated correlation of events and metrics, AI-driven insights, explainability of findings, noise reduction, and intelligent alert prioritization. |
| Cloud and infrastructure context | Application slowdowns often originate outside the application itself. Infrastructure context helps teams distinguish between application defects and underlying platform, network, or resource issues. | Coverage across hybrid and multi-cloud environments, containers, Kubernetes, virtual machines, storage systems, networking components, infrastructure dependencies, and topology visualization. |
| Automation | Automation reduces manual effort, improves operational consistency, and helps IT teams manage large-scale environments while responding proactively to emerging issues. | Automated discovery, dynamic baselining, anomaly detection, event correlation, alert suppression, workflow automation, remediation capabilities, and integration with IT operations tools. |
| Commercial fit | Even technically strong solutions must align with budget, operational requirements, and long-term business goals to ensure sustainable adoption and return on investment. | Deployment models, data retention options, ecosystem integrations, licensing flexibility, pricing predictability, scalability, implementation effort, and overall total cost of ownership (TCO). |
How to Choose the Right APM Tool: Final Checklist
The right application performance monitoring tool is the difference between guessing at 2 a.m. and knowing. When applications and infrastructure are unified in one view, you stop chasing symptoms across disconnected dashboards and start fixing root causes fast.
To see what end-to-end APM looks like in practice, look at how eG Enterprise correlates application performance with the full stack beneath it. Better to see the whole picture before your next incident, not during it.
eG Enterprise is an Observability solution for Modern IT. Monitor digital workspaces,
web applications, SaaS services, cloud and containers from a single pane of glass.
Frequently Asked Questions
An application performance monitoring tool measures how well your applications perform and helps teams fix problems affecting speed, availability, and user experience. It collects metrics like response time, throughput, and error rates, then correlates them so teams can detect issues and find root causes quickly.
Application monitoring tools instrument application code, watch the supporting infrastructure, and observe real user activity. They gather telemetry across these layers, baseline normal behavior, and analyze deviations. By correlating signals from every tier, they pinpoint where a problem originates, not just where symptoms appear.
APM focuses on measuring application performance through predefined metrics and transactions. Observability is broader, using metrics, logs, and traces to understand a system's internal state, including conditions you did not anticipate. In practice, modern APM platforms increasingly include observability capabilities for deeper, more flexible analysis.
Cloud applications run across distributed, often multi-cloud environments where components scale and move constantly. APM gives you visibility into that complexity, tracing transactions wherever they run and correlating performance with cloud infrastructure. Without it, problems hide in the gaps between services and cloud-native tools.
Any industry that depends on digital services benefits, especially those with mission-critical applications. Healthcare, finance, banking, government, manufacturing, and education all rely on APM to keep core systems performing. The more revenue depends on application uptime, the greater the value of APM.
Choosing an Application Performance Monitoring (APM) tool begins with identifying your most critical applications and business services. Evaluate technology coverage, monitoring depth, scalability, integrations, deployment options, and reporting capabilities. Shortlist solutions that fit your budget, then validate them using real workloads to assess visibility, usability, and diagnostic accuracy.
Look for an APM tool that provides end-to-end transaction tracing, real user monitoring, synthetic testing, and full-stack visibility across applications and infrastructure. Strong root-cause analysis, intelligent alerting, automation, broad technology support, scalable architecture, comprehensive reporting, and predictable pricing are also essential for long-term operational success.
A modern APM tool should include transaction monitoring, distributed tracing, code-level diagnostics, real user monitoring, synthetic monitoring, and application dependency mapping. Additional capabilities such as anomaly detection, automated baselining, topology visualization, AI-assisted insights, and application-to-infrastructure correlation help teams detect, diagnose, and resolve performance issues faster.
Evaluate APM tools using consistent testing scenarios that reflect your production environment and business-critical workloads. Compare implementation effort, ease of use, monitoring coverage, diagnostic accuracy, scalability, reporting quality, integrations, and alert effectiveness. Consider both short-term deployment requirements and long-term total cost of ownership before making a decision.
APM pricing can vary based on several factors, including the number of monitored hosts, applications, transactions, containers, cloud resources, and telemetry data collected. Data retention periods, advanced analytics modules, deployment models, support levels, and licensing structures also influence overall costs and determine long-term budget predictability.
When selecting an APM tool for cloud applications, prioritize support for dynamic environments, containerized workloads, and Kubernetes platforms. Look for distributed tracing, cloud service visibility, OpenTelemetry compatibility, automated discovery, and multi-cloud monitoring. Effective correlation across applications, infrastructure, and cloud services is critical for rapid root-cause identification.


